Agile quadruped locomotion that transfers to the real world
Real robots need gaits that hold up outside the training setup. I use reinforcement learning to get quadrupeds through tight 3D spaces, run them at high speed, and transfer policies to robot bodies they were never trained on, with deployment on real Unitree robots.
Traversing confined spaces
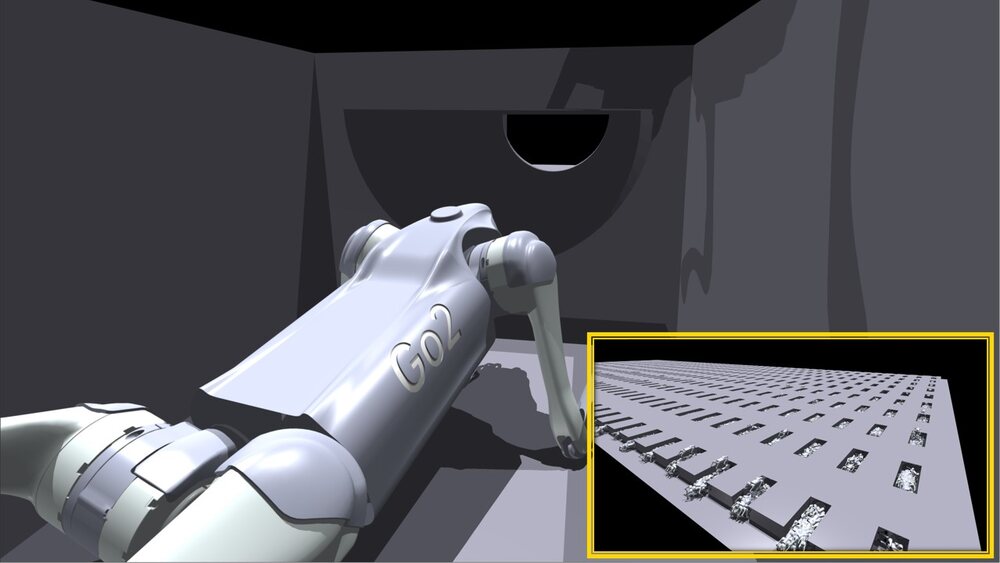
Crawling and squeezing through tunnels and irregular 3D voids.
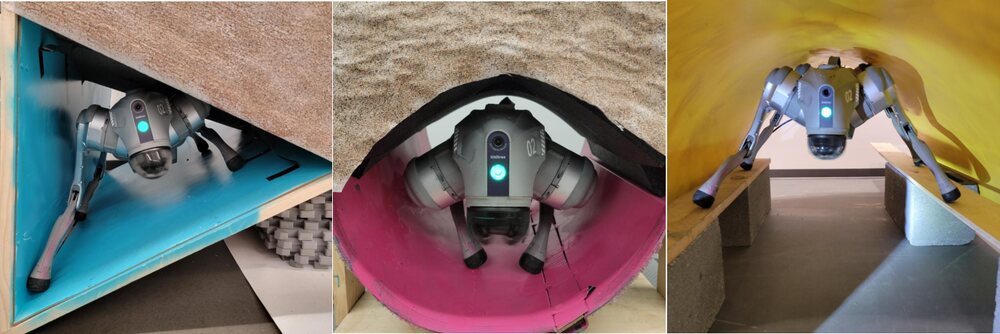
Robot Squid Game: Quadrupedal Locomotion for Traversing Narrow Tunnels
SQUID trains expert policies on procedurally generated tunnels and distills them into one vision-based student policy, validated in real-world tunnel deployments.

Dexterous Legged Locomotion in Confined 3D Spaces with Reinforcement Learning
Learns locomotion skills end-to-end from goal-directed navigation in confined 3D spaces, with a classical planner setting waypoints for an RL policy. Deployed on a real robot.
High-speed locomotion
Curricula that raise commanded speed without losing stability.
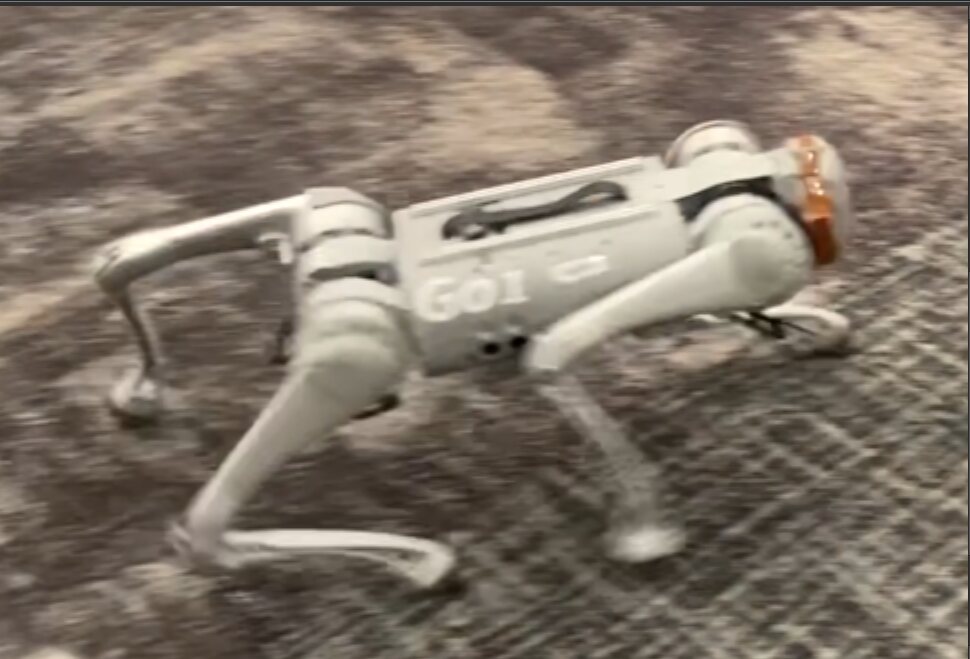
TransCurriculum: Multi-Dimensional Curriculum Learning for Fast & Stable Locomotion
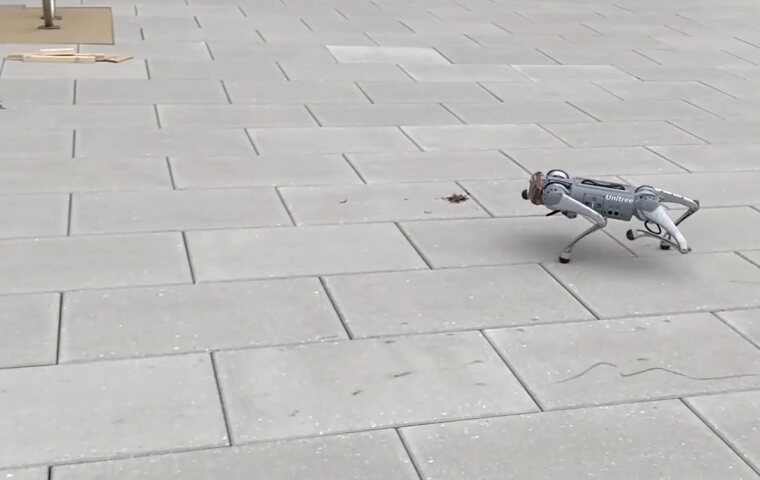
A transformer teacher schedules command velocity, terrain difficulty, and domain randomization together, reaching 4.1 m/s on a real Unitree Go1.
HACL: History-Aware Curriculum Learning for Fast Locomotion
A recurrent network models the history of velocity commands and rewards to drive the curriculum, reaching a peak forward velocity of 6.7 m/s.
Transfer across robot bodies
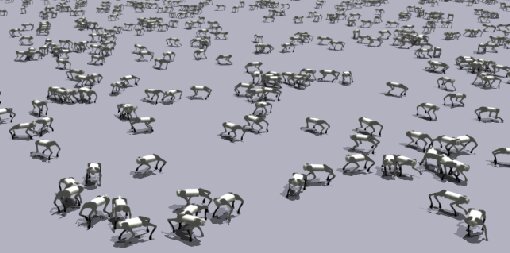
One policy, many morphologies, and no fine-tuning on the new robot.
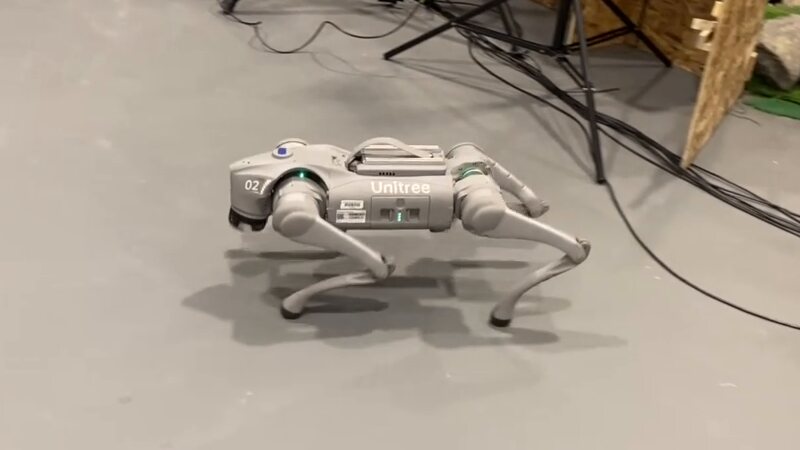
MorFiC: Fixing Value Miscalibration for Zero-Shot Quadruped Transfer
A FiLM-modulated critic conditioned on each robot's physical and control parameters fixes value miscalibration in shared training. Tested on real Go1 and Go2 robots without fine-tuning.
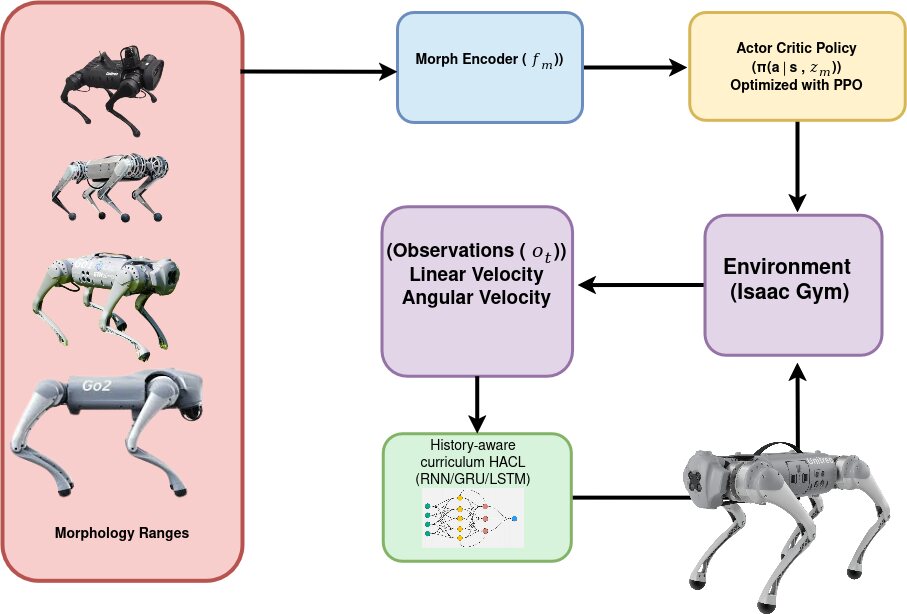
McARL: Morphology-Control-Aware Reinforcement Learning for Generalizable Quadrupedal Locomotion
Conditions actor and critic on a randomized morphology vector, so a policy trained on a Go1 transfers zero-shot to a Go2 at up to 3.5 m/s.